 Repository
 Research
FOCA · cair-vinuni
FOCA studies future-oriented conditioning for data-efficient VLA adaptation.
Vision-language-actionTHE EMBODIED AI DIRECTORY
Explore vision-language-action models and robotics foundation models with official project links.
Repository
Research
FOCA studies future-oriented conditioning for data-efficient VLA adaptation.
Vision-language-action Repository
 Research
Uni-NaVid: A Video-based Vision-Language-Action Model for Unifying Embodied Navigation Tasks.
Vision-language-action Repository
 Research
From Vision-Language-Action Models to a Real-World Robot Learning Stack
Vision-language-action Repository
 Research
VLA-0 provides research code for building vision-language-action models from vision-language models.
Vision-language-action Repository
 Research
Green-VLA: Staged Vision-Language-Action Model for Generalist Robots
Vision-language-action Repository
 Research
VLA-RFT provides reinforcement fine-tuning resources for vision-language-action models.
Vision-language-action Repository
 Research
WholebodyVLA studies latent VLA representations for whole-body locomotion and manipulation.
Vision-language-action Repository
 Research
The official repository of the first version of ACE-Brain foundation model.
Vision-language-action Repository
 Research
Anchor-Align studies VLA fine-tuning with representation anchoring and language-action alignment.
Vision-language-action Repository
 Research
BitVLA implements 1-bit vision-language-action models for robotic manipulation.
Vision-language-action Repository
 Research
CATok studies causal action tokenization for robot policies with conditional annealing in flow matching.
Vision-language-action Repository
 Research
CLP-VLA provides layer-focused fine-tuning and evaluation code for VLA models.
Vision-language-action Repository
 Research
DEAS Isaac GR00T provides setup resources combining DEAS, Isaac GR00T and RoboCasa.
Vision-language-action Repository
 Research
Dexora provides VLA policy resources for high-degree-of-freedom bimanual dexterity.
Vision-language-action Repository
 Research
DynamicVLA provides research resources for dynamic-object robotic manipulation.
Vision-language-action Repository
 Research
EAI2025 Project combines 3D semantic mapping and VLA deployment for manipulation.
Vision-language-action Repository
 Research
Emma-X: An Embodied Multimodal Action Model with Grounded Chain of Thought and Look-ahead Spatial Reasoning
Vision-language-action Repository
 Research
FLUX 3 Action provides world-action modeling and action-prediction resources for robots and simulators.
Vision-language-action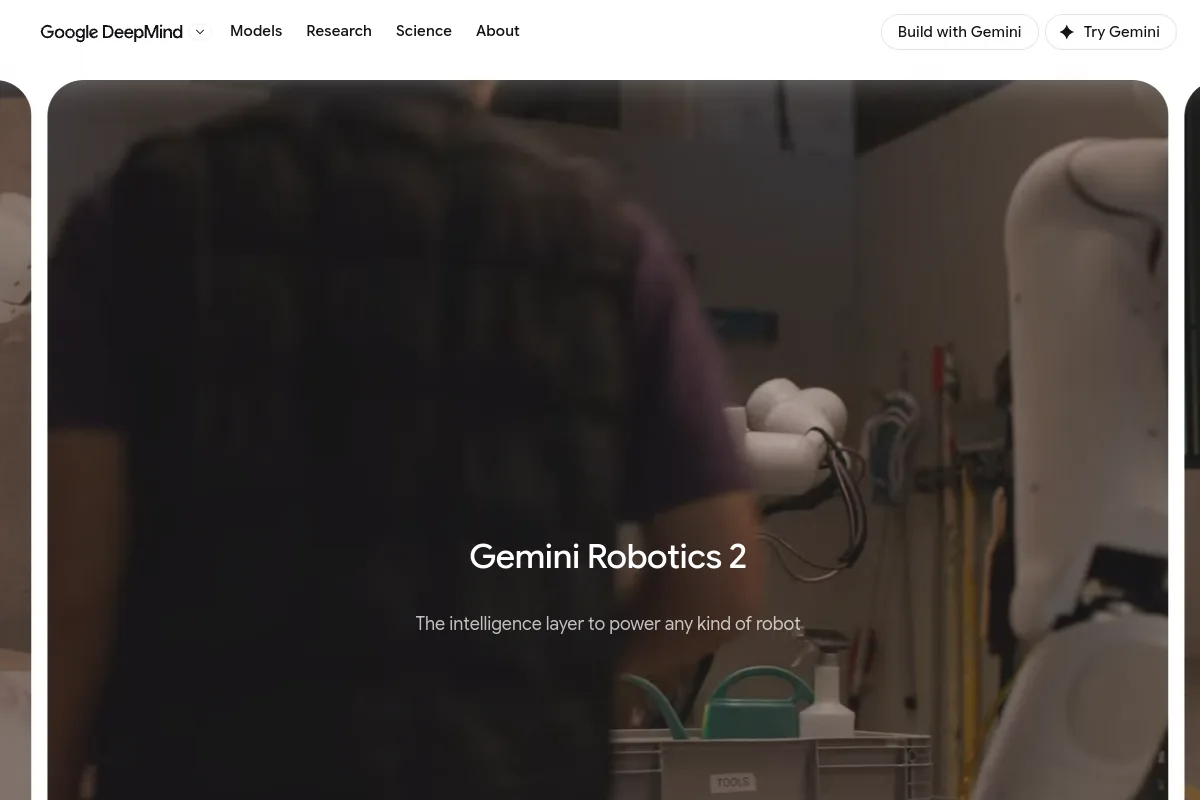 Website
 Research
Google DeepMind robotics models connecting perception and action.
Vision-language-action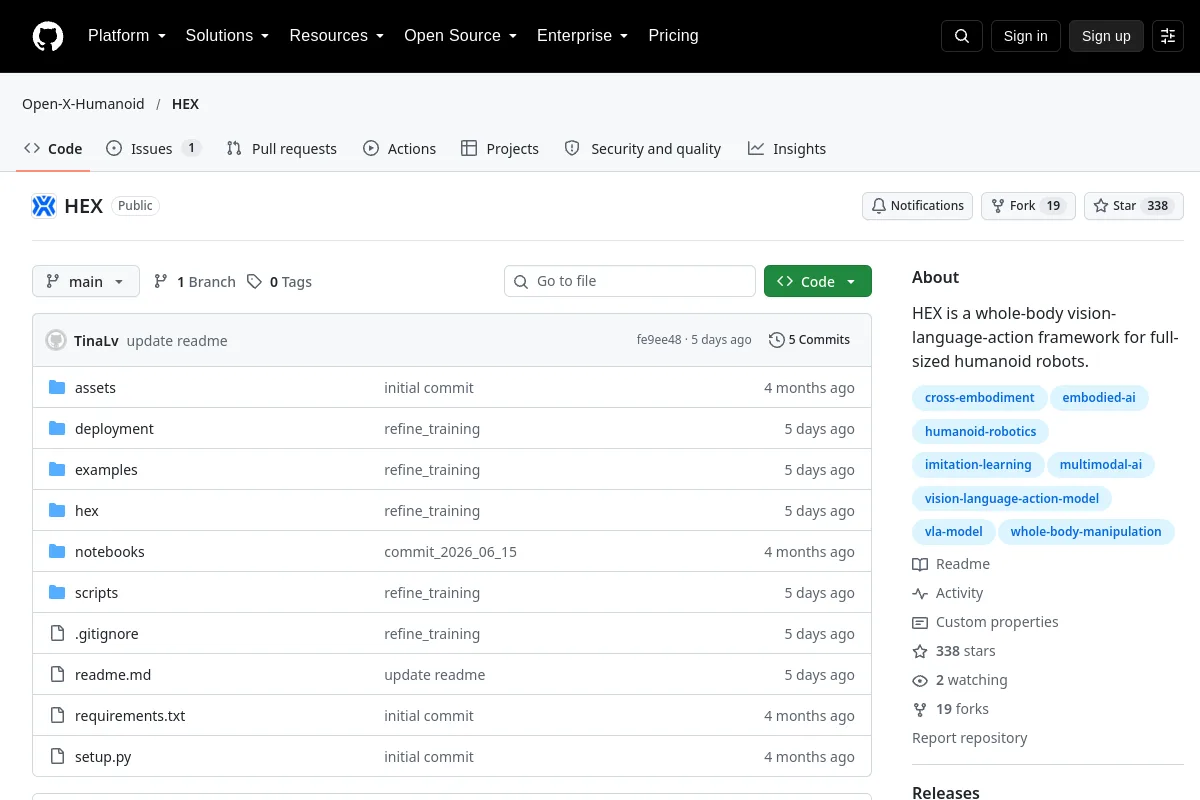 Repository
 Research
HEX is a whole-body vision-language-action framework for full-sized humanoid robots.
Vision-language-action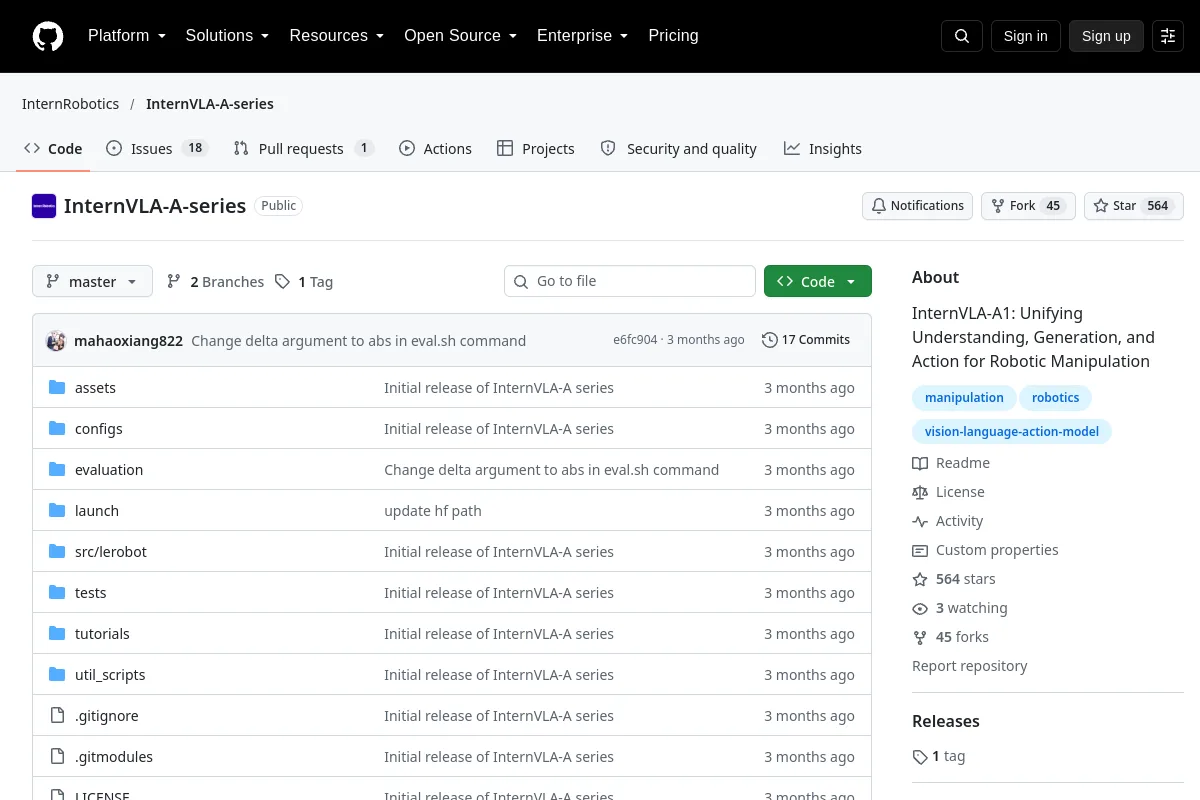 Repository
 Research
InternVLA-A series studies understanding, generation and action for robotic manipulation.
Vision-language-action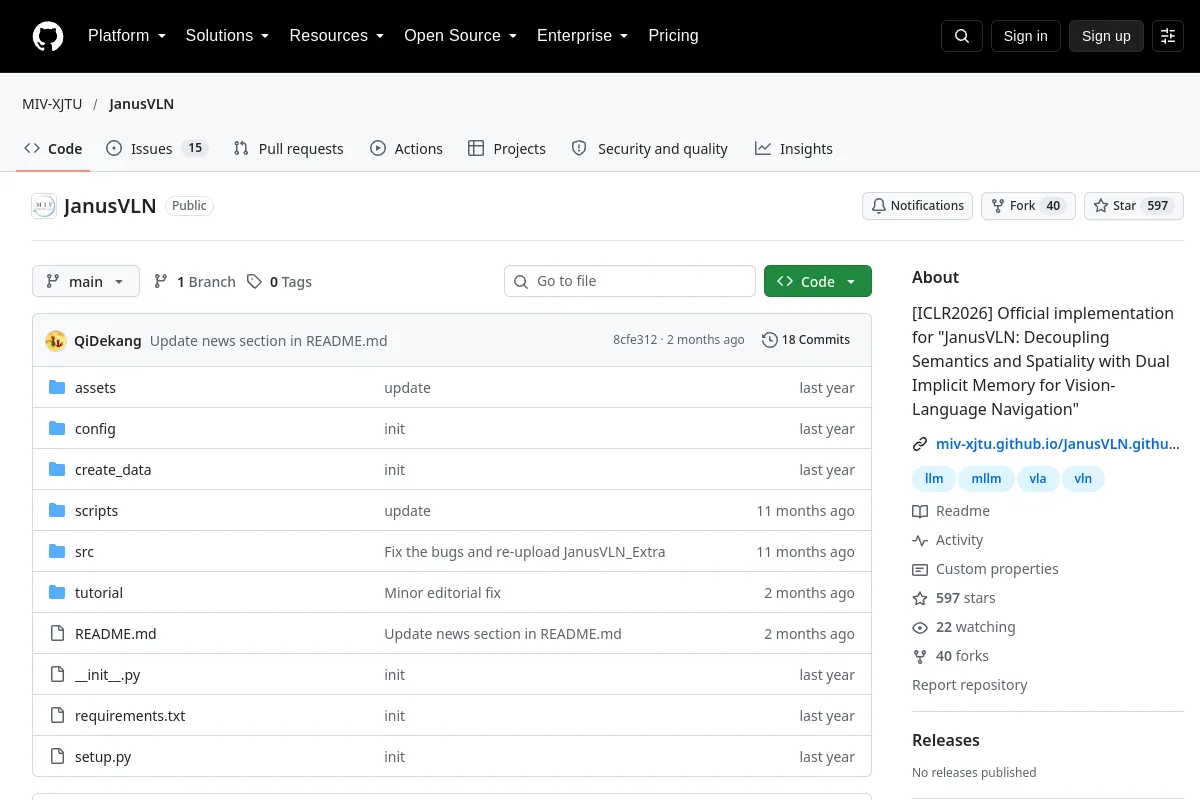 Repository
 Research
JanusVLN studies vision-language navigation with separate semantic and spatial memory.
Vision-language-action Repository
 Research
Code of paper "KERV: Kinematic-Rectified Speculative Decoding for Embodied VLA Models" accepted by DAC 2026.
Vision-language-action Repository
 Research
LaST$_0$: Latent Spatio-Temporal Chain-of-Thought for Robotic Vision-Language-Action Model
Vision-language-actionSELECTION NOTES
Check supported observations and action representations, checkpoint licenses, compute requirements and adaptation datasets. Model weights do not provide a ready-made controller for every robot. Plan evaluation in simulation and controlled hardware tests.
Know a resource that belongs here?