 Website
 Research
openpi
Code and model resources for Physical Intelligence robot policies.
Vision-language-action
Models / Research
ACOT-VLA-WM is an advanced Vision-Language-Action robotics framework that uses a predictive world model to generate visual subgoals, improving long-horizon robotic manipulation accuracy and…
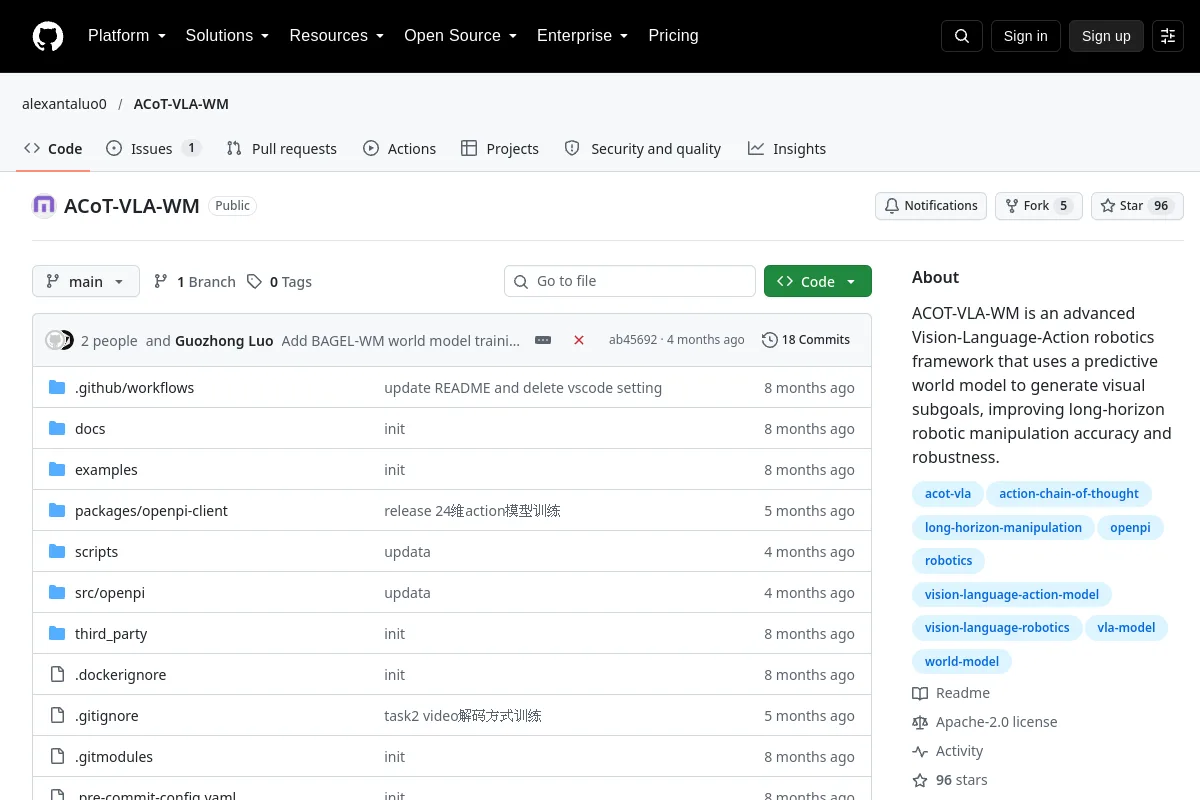
ACOT-VLA-WM is an advanced Vision-Language-Action robotics framework that uses a predictive world model to generate visual subgoals, improving long-horizon robotic manipulation accuracy and…
Publisher purpose: ACOT-VLA-WM is an advanced Vision-Language-Action robotics framework that uses a predictive world model to generate visual subgoals, improving long-horizon robotic manipulation accuracy and robustness.
Review observation/action interfaces, checkpoints, robot embodiments and adaptation requirements. Repository code licensing does not automatically license weights or training data.
Code licenses do not automatically cover model weights, datasets or hardware designs. Unrecorded license details require confirmation with the publisher.
Website
Research
Code and model resources for Physical Intelligence robot policies.
Vision-language-action