 Repository
 Research
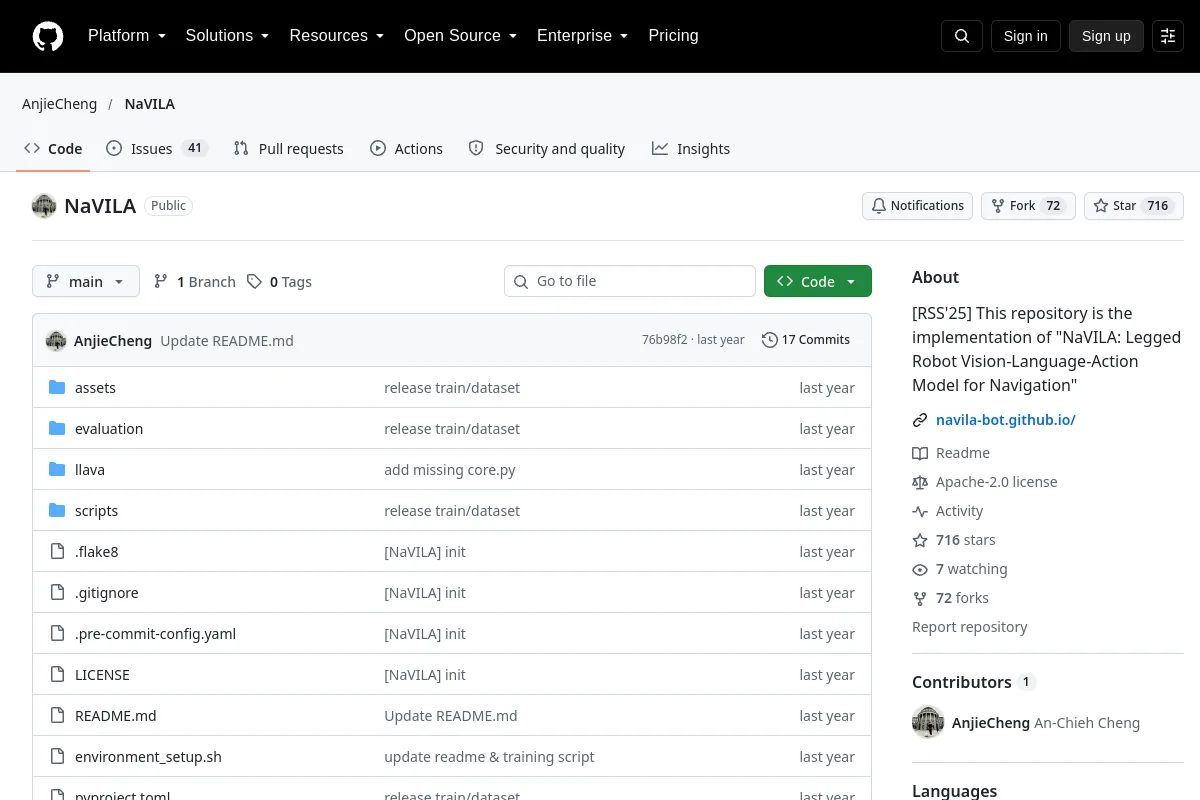
NaVILA · AnjieCheng
This repository is the implementation of "NaVILA: Legged Robot Vision-Language-Action Model for Navigation"
Vision-language-action
Models / Research
MobileVLA-R1: Reinforcing Vision-Language-Action for Mobile Robots
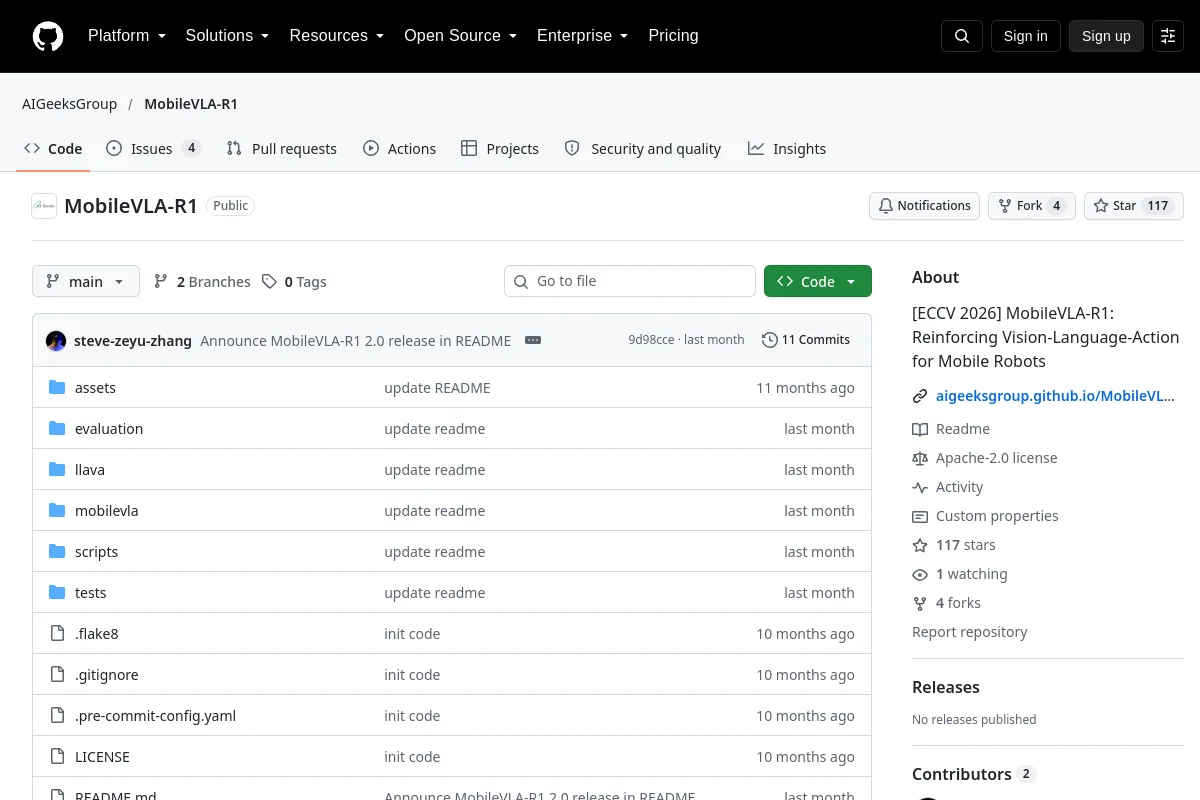
MobileVLA-R1: Reinforcing Vision-Language-Action for Mobile Robots
Publisher purpose: [ECCV 2026] MobileVLA-R1: Reinforcing Vision-Language-Action for Mobile Robots
Review observation/action interfaces, checkpoints, robot embodiments and adaptation requirements. Repository code licensing does not automatically license weights or training data.
Code licenses do not automatically cover model weights, datasets or hardware designs. Unrecorded license details require confirmation with the publisher.
Repository
Research
This repository is the implementation of "NaVILA: Legged Robot Vision-Language-Action Model for Navigation"
Vision-language-action